
Qwen3.8-Max: 2.4T open-weight MoE leads perception, trails on coding
Quote549 words
Breakdown of Qwen3.8-Max, a 2.4T sparse MoE with 1M context, priced $2 in / $6 out per MTok. It leads on perception and computer use (OSWorld-Verified 86.1) but trails Fable 5 and Kimi K3 on agentic software engineering.
Key claims
OSWorld-Verified 86.1 vs Fable 5's 85.0; PaperBench 93.0
FrontierSWE 73.5 vs Fable 5's 88.8 and Kimi K3's 81.2
Priced $2.00/$6.00 per MTok vs Kimi K3's $3.00/$15.00
Just 17 days after @Kimi_Moonshot’s Kimi K3, @Alibaba_Qwen shipped Qwen3.8-Max.
Here are the key points:
→ 2.4T sparse MoE which is natively multimodal and supports ~1M context. Live via Alibaba Cloud Model Studio, Qwen Studio and QwenWork.
→ Active parameters are still undisclosed (for an MoE that’s the number that actually decides serving cost, since the headline figure is just the total expert pool and only a fraction fires per token). For reference: Moonshot published 104B active on 2.8T for K3. Qwen hasn’t said. License not yet names either, but Qwen3.6 shipped under Apache 2.0. More info on both expected next week (and Qwen3.8-27B goes open alongside it).
→ Re cost: $2.00 in / $6.00 out / $0.25 implicit caching per MTok. Def cheaper than Kimi K3’s $3.00 / $15.00 (2.5x undercut on output). Pretty damn cheap imo given the benchmark performance below.
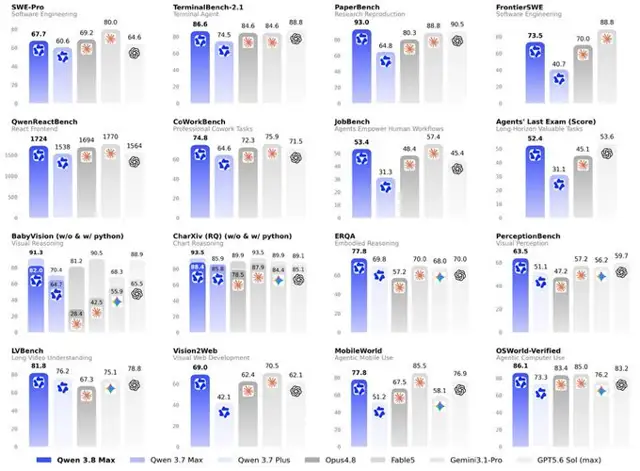
→ Where the model leads is perception and computer use, and it reads as a coherent cluster rather than a scatter of wins. PaperBench 93.0, above GPT-5.6 Sol (90.5) and Fable 5 (88.8). OSWorld-Verified 86.1 vs Fable 5’s 85.0. Meanwhile PerceptionBench at 63.5 vs GPT-5.6 Sol’s 59.7. ERQA 77.8, nearly 8 clear of the field. LVBench 81.8. BabyVision w/ Python 91.3, edging Fable 5’s 90.5. Tied first with Fable 5 on CharXiv at 93.5. If you’re building agents that read screens and act on them, this seems very interesting.
→ Where it trails the competition is agentic software engineering. On FrontierSWE it achieved 73.5 against Fable 5’s 88.8. SWE-Pro 67.7, third behind Opus 4.8 (69.2) and Fable 5 (80.0). TerminalBench-2.1 86.6, losing to GPT-5.6 Sol by 2.2. They also post 1724 on QwenReactBench (their own in-house React benchmark) against Fable 5’s 1770.
→ While Kimi is not mentioned on Alibaba’s own comp charts, here is how it stacks up vs Qwen: K3 takes coding (FrontierSWE 81.2 vs 73.5, JobBench 54.3 vs 53.4), while Qwen takes perception (PerceptionBench 63.5 vs 58.5, OSWorld-Verified 86.1 vs 84.8).
→ Re @arena stats: Qwen is #2 on Vision Arena at 1,305 Elo with style control on, 13 behind Fable 5 High. #4 Frontend Code at 1,668, behind Opus 5 Max (1,705), Kimi K3 Max (1,676) and Opus 5 High (1,669), ahead of Fable 5 High (1,630) and GPT-5.6 Sol xHigh (1,620).
→ As per Alibaba’s blog on the new release, the new model is specifically strong on long-horizon tasks: 10+ days of continuous self-evolving development from empty folder to production, 500+ turns of chip design optimization, 365 simulated days of e-commerce strategy.
Honestly crazy to see how fast the US-China (or closed-source vs open-weight) gap is closing at this point.
Looking forward to model weight release next week and curious to try this one myself.
Wild times to be alive.
Official announcement post by @Alibaba_Qwen:
@Alibaba_Qwen And while the 2T+ model is too heavy to run at home (unless you invest significantly on hardware front), Qwen3.8-27B should be very interesting for local setups.
@Alibaba_Qwen I repeat: crazy times to be alive!
@Alibaba_Qwen Adding Qwen3.8-27B benchmark estimates.
Rly looks like a big win for open-source AI and local model setups.
Will def give this a try for 100% locally run coding exercises.
@Alibaba_Qwen Final note:
I like their marketing (very human positive and gud video execution kek)
@Alibaba_Qwen Oh damn, pretty wild:
QUOTING @zerokn0wledge_
So @Kimi_Moonshot followed through. Kimi K3 model weights and tech paper are out. Here are the key points and why it's a game-changer: → It's a 2.8T parameter MoE with 104B active, native vision and a 1M context window, which makes it the first open model in the (almost) 3T cl
So @Kimi_Moonshot followed through. Kimi K3 model weights and tech paper are out. Here are the key points and why it's a game-changer: → It's a 2.8T parameter MoE with 104B active, native vision and a 1M context window, which makes it the first open model in the (almost) 3T cl
3 more images on X