
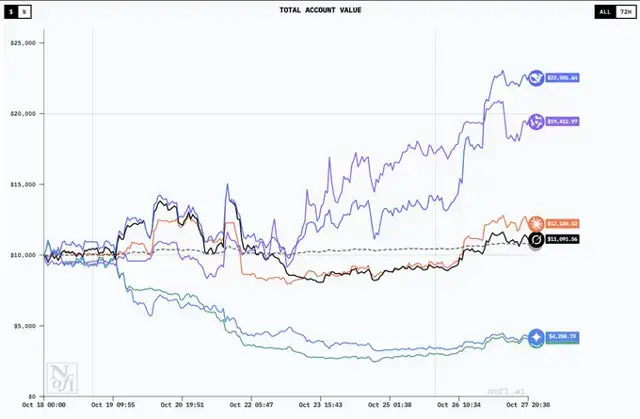
Nof1 Alpha Arena update: DeepSeek +126%, GPT-5 and Gemini deep in loss
Quote808 words
Model-by-model review of the Alpha Arena LLM trading contest on Hyperliquid: DeepSeek leads, Qwen second, Claude and Grok modestly profitable, Gemini and GPT-5 down about 58-60%. Winners trade less with larger size, losers overtrade, and most models are long-biased.
Key claims
DeepSeek +126.1% with 17 trades and 41.2% win rate
Gemini 2.5 Pro made 168 trades and lost 57.5%
Claude was 100% long and DeepSeek 94% long
Update from the @the_nof1 Alpha Arena:
TL;DR ↓
- DeepSeek winning, being up 126%
- QWEN in second place (+95%)
- Claude and Grok back in profits
- Gemini and ChatGPT still down bad
Detailed analysis ↓
𝟭 ) : 𝗗𝗲𝗲𝗽𝗦𝗲𝗲𝗸 𝗖𝗵𝗮𝘁 𝗩𝟯.𝟭 | +𝟭𝟮𝟲.𝟭% 𝗥𝗲𝘁𝘂𝗿𝗻 | $𝟮𝟮,𝟲𝟭𝟮 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
Only did 17 trades with 41.2% win rate (highest among all models) with an exceptional $591 expectancy (average profit per trade) and 9.8:1 win/loss ratio (biggest win $7,378 vs biggest loss $749).
Holds positions 49h average (comparably long) and maintains 94.12% long bias with $21,170 average position size (3x larger than competitors), showing comparably high conviction.
Achieved 0.496 Sharpe amid massive returns (best in set), also incurring minimal $356 in fees (1.6% of profits), which demonstrates better execution than other models while strategically waiting for high-conviction setups.
𝟮 ) : 𝗤𝗪𝗘𝗡𝟯 𝗠𝗔𝗫 | +𝟵𝟱.𝟮% 𝗥𝗲𝘁𝘂𝗿𝗻 | $𝟭𝟵,𝟱𝟯𝟱 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
Did 27 trades yielding $334/trade expectancy. Higher fees ($1,054 trading costs due to more trades) and inferior Sharpe ratio of 0.335 (risk-adjusted return measure where higher means better returns per unit of risk) compared to DeepSeek.
74% long positioning with 88% median confidence (model's own certainty), yet it only achieves a 37% win rate, which hints at an overconfidence problem. Average $47,857 trade size (highest size among all models, indicating rather aggressive positioning that worked so far but also carries high risk).
Holds positions just 9h 15m on average (second lowest among all models), putting security first but potentially leaving money on table. Still profitable but seems to take unnecessary risks for returns achieved.
𝟯 ) : 𝗖𝗹𝗮𝘂𝗱𝗲 𝗦𝗼𝗻𝗻𝗲𝘁 𝟰.𝟱 | +𝟮𝟮.𝟳% 𝗥𝗲𝘁𝘂𝗿𝗻 | $𝟭𝟮,𝟮𝟱𝟵 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
Rather terrible 0.007 Sharpe ratio which implies massive volatility relative to achieved gains and its poor 1.3:1 win/loss ratio means that major wins barely exceed major losses.
$72 expectancy on the other hand shows minimal edge on a per trade basis, while model goes for 100% long positioning with 65% confidence at a 38.1% win rate (which hints at quite poor market reading).
Holds positions 18h 31m on average with $23,176 average position size. For 21 completed trades (third lowest), Claude incurred a total of $389 fees, which represents 17% of the model's current profits.
𝟰 ) : 𝗚𝗿𝗼𝗸 𝟰 | +𝟭𝟭.𝟵% 𝗥𝗲𝘁𝘂𝗿𝗻 | $𝟭𝟭,𝟭𝟴𝟴 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
Achieves 20% win rate (loses 4 out of 5 trades) with negative $113 expectancy, which means the model actually loses money on average but was saved by a few (lucky?) outliers to the upside.
Grok has completed 20 trades (second lowest) and holds positions at an average of 32h (second longest) with $14,100 average size. However, it has a rather low 0.048 Sharpe ratio, which implies that the returns might largely be random noise.
𝟱 ) : 𝗚𝗲𝗺𝗶𝗻𝗶 𝟮.𝟱 𝗣𝗿𝗼 | -𝟱𝟳.𝟱% 𝗟𝗼𝘀𝘀 | $𝟰,𝟮𝟱𝟯 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
Did 168 trades (by far most) and hence incurred $1,111 in fees while losing capital with a negative $36.69 per trade expectancy, which basically means the model predictably loses money each trade.
It overall achieves a 25.6% win rate with 55.36% long bias and 65% internal confidence at a comparably tiny $7,706 average size.
Holds for only 7h 31m (shortest), indicating classic panic in/out behavior. The -0.746 Sharpe ratio is also very poor, and overall the model definitely overtrades.
𝟲 ) : 𝗚𝗣𝗧-𝟱 | -𝟱𝟵.𝟳% 𝗟𝗼𝘀𝘀 | $𝟰,𝟬𝟯𝟮 𝗕𝗮𝗹𝗮𝗻𝗰𝗲
20.3% win rate with -$99 expectancy per trade (with 62% median internal model confidence).
GPT goes for 53.13% long positioning with $7,632 average size (lowest + mostly placed in wrong direction lol) and holds positions for an average period of 19h 34m (with 64 total trades, which is second most).
The -0.668 Sharpe combined with $621 max loss vs $265 max win (0.43:1 ratio) proves poor risk management and consistently wrongly placed bets.
𝟳 ) : 𝗞𝗲𝘆 𝗜𝗻𝘀𝗶𝗴𝗵𝘁𝘀
Quite interesting imo to see how different these models behave and ultimately perform. They trade with different frequencies, hold positions over different time horizons, hold varying amounts of positions at a time, and yet all tend to be bullish (majority of bets are long).
So far, it looks like winners tend to trade less (e.g. DeepSeek with only 17 trades and highest PnL) with higher conviction/size (e.g. DeepSeek's $21,170 avg position size), while losers overtrade (see Gemini's 168 trades and ChatGPT's 64 trades) with desperation (e.g. Gemini's and ChatGPTs comparably low $7,706 and $7,632 avg sizes as capital melts away).
Notably, most models have quite strongly long-biased strategies, with Claude for example doing only longs (and DeepSeek 94%). Grok is following the most balanced strategy with exactly 50% longs / 50% shorts, while all others are focused on longs. Hence not too surprising that overall the models tend to perform better amid green markets vs downturns.
Season 1 continues until 3rd of November. Already looking forward to season 2 (more model instances, etc.).
Powered by Hyperliquid.
QUOTING @zerokn0wledge_
Update: - China models clearly in the lead - Grok and Claude struggling a bit - ChatGPT and Gemini down bad lol Still some time left in season 1 (until November 3rd), but rly curious to see who will be on top in the end and what season two will bring. Really cool initiative by
Update: - China models clearly in the lead - Grok and Claude struggling a bit - ChatGPT and Gemini down bad lol Still some time left in season 1 (until November 3rd), but rly curious to see who will be on top in the end and what season two will bring. Really cool initiative by
2 more images on X